3 TALCO
0. Innovation
- TALCO-WFAA is the first accelerator based on the WFA-Adapt algorithm capable of performing arbitrary long sequence alignments.
- TALCO allows a memory-constrained accelerator to fall back to the host when a frontier size exceeds the maximum size it can handle to guarantee equivalent alignment results with and without tiling, a feature that is missing in the previous tiling approaches.
1. Motivation
The high memory demands of long alignments create significant obstacles to hardware acceleration. Tiling-based hardware accelerators have made remarkable strides in accelerating sequence alignment. Existing tiling heuristics can cause the alignment quality to degrade.
Based on Amdahl's law, there is diminishing return to accelerate this step further over the three to four orders of magnitude speedup already achievable with tiling-based accelerators. Instead, for wider adoption, future hardware accelerators should commensurately focus on improving and guaranteeing alignment quality.
2. proposal
TALCO – a novel method for tiling long sequence alignments maintains a constant memory footprint during the acceleration step independent of alignment length. However, unlike previous techniques, TALCO also ensures optimal alignments under banding constraints. TALCO does this by leveraging the convergence of traceback paths beyond a tile to a single point on the boundary of that tile.
- tiling alignments using the convergence of traceback pointers.
- highly generalizable strategy that can be used to perform tiling on a wide range of banded alignment algorithms while ensuring alignment result equivalence.
3. insight
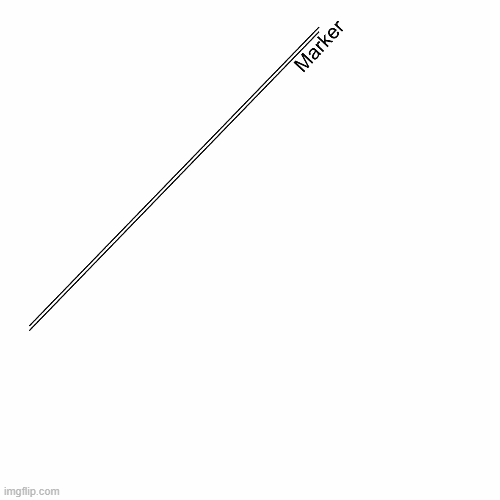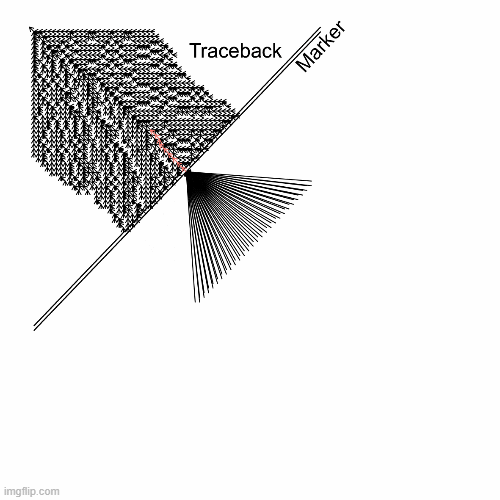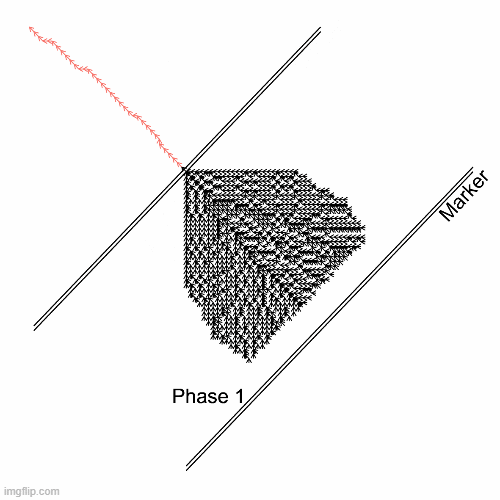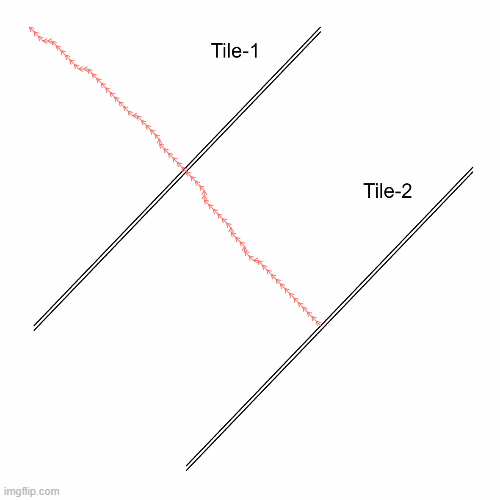
Traceback pointers in alignments have weak long-range dependencies, resulting in the convergence of multiple alignment paths.
4. background
1). Needleman-Wunsch algorithm
- solves the global sequence alignment problem
- allowing the flexibility to reward each combination of matching or mismatching characters in the alphabet differently in the alignment score.
2). Smith-Waterman algorithm
- find local sequence alignments, i.e., substrings of the input sequences that align with the maximum score.
3). traceback matrix
Both algorithms compute a traceback matrix of size , where each cell of the matrix points to one of its adjacent cells (up, left, or diagonal) indicating the direction to arrive at that cell with the maximum score. The optimal alignment(s) between the two sequences is determined by following a path(s) of traceback pointers in this matrix. Both algorithms have a time and space complexity of .
Affine gap scoring increases the memory requirement for storing traceback pointers in these algorithms by a constant factor.
- The affine gap scoring method does not alter the algorithm’s asymptotic complexity on its own, but it requires each cell to maintain multiple DP states simultaneously, resulting in memory usage for backtracking pointers that is a constant multiple higher than that of the linear gap approach.
- In affine gaps, to distinguish between “opening a gap” and “extending a gap,” it is necessary to maintain three states—match, insert, and delete—and each state requires storing its own score and backpointer. As a result, the storage required for backpointers increases by a constant factor (about 3 times), but the asymptotic complexity remains unchanged.
4). WFA
- The algorithm that produces optimal global alignments based on Levenshtein distance.
- uses a triangular-shaped traceback matrix
- columns correspond to the diagonals of the DP matrix
- rows correspond to the alignment score
- WFA [38] is a recent extension of the algorithm to support affine gaps and generalized distance measures.
- supporting affine-gap penalties result in a constant-fold increase in the memory requirement.
- BiWFA is a recent extension of WFA that trades runtime for memory efficiency, but it still requires up to hundreds of megabytes for long and noisy alignments.
5). banding techniques
Banding techniques improve the speed and memory requirements of the alignment algorithms by heuristically pruning the search space. X-Drop has been a popular banding technique for classical DP algorithms
- A running maximum score is maintained in a systolic fashion.
- A stripe calculation terminates when scores of all cells along a column drop below .
6). tiling techniques
To make alignment more amenable to hardware acceleration, a tiling heuristic, called GACT, was introduced in Darwin and later adapted in other accelerators.
This technique extends an alignment using a series of overlapping tiles, with tile size and overlap determined by fixed parameters, and . It required only memory, corresponding to a single tile of the alignment and independent of the lengths of sequences being aligned, to be maintained on-chip (the traceback path was stored offchip in memory), allowing arbitrary long alignments to be accelerated in hardware with high speedup.
5. Tiling Algorithm
Phenomenon: alignment paths starting from different cells on the wavefront merge at a single cell in the matrix, highlighted with a blue circle, and then share a common path to the origin (i.e., the top-left cell).
Such convergence of traceback pointers from nearby cells is a prevalent characteristic observable in many alignments and closely resembles the "rank convergence" property of dynamic programming algorithms found in a previous paper.
Principle: rank convergence is frequently observed because the score dependence between two cells in the DP matrix weakens as their distance increases, which we observe is also the case with traceback pointers.
1). Frontier
The frontier, is defined as a set of cells in the traceback matrix such that the scores and traceback pointers(enum, bitfield type) for cells in depend only on the previous frontier, .
2.) Marker
A marker is a special frontier in the TALCO algorithm that is used to separate the two phases of the TALCO algorithm.
3). traceback pointer
A traceback pointer is a scalar, a very small discrete tag/bitfield, with one stored in each DP cell.
- For Needleman-Wunsch, each pointer represents three possibilities: from the diagonal, from above, or from the left.
- For affine gap:
- 2 bits: indicates whether H comes from I, D, or diagonal
- 1 bit: indicates whether I is extended or newly opened
- 1 bit: indicates whether D is extended or newly opened
4.) convergence pointer
- pointer redirection
- reduction tree to detect convergence
5). traceback path
Phase 1: Compute normally, store traceback pointers
↓
Reach marker
↓
Phase 2: Propagate convergence pointers, wait for convergence
↓
Determine (traceback start point))
↓
Traceback Logic traces back along pointers from
↓
Obtain partial alignment for current tile
↓
Concatenate partial alignments from all tiles
↓
Complete traceback path
6. TALCO accelerator design
The accelerator is implemented as a co-processor.
- Host CPU + controller + PE array + Device Memory
- Host CPU issues alignment tasks along with the addresses of sequence pairs to be aligned to parallel TALCO-Align units and receives the output.
- Host CPU also performs alignments that fail because of frontier lengths exceeding the hardware constraints. The overhead for failed alignments corresponds to the alignment speed of the software.
hardware internal structure
1). TALCO-XDrop
- PE Array: A set of processing units arranged in a systolic manner.
- FIFO: Temporarily stores the H and D values of the last row of the previous stripe.
- Traceback Pointer SRAM: Dedicated to each PE, stores traceback pointers.
- Start/Stop SRAM: Stores the start and end positions of each stripe.
- Reduction Tree: Determines whether convergence pointers computed by multiple PEs converge to the same cell.
- Convergence Pointer SRAM: Stores the convergence result of each wavefront(ConvPrprev and ConvPrcurr).
- Traceback Logic: Starts backtracking from the convergence point or the maximum score point.
- Registers , : Track the maximum score.